Home/Blog/DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office
human + AI workflows
DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office
DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office The landscape of artificial intelligence is rapidly evolving, with sophisticated models becoming the
11 MIN READ
30 Oct 2026
human + AI workflows
DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office
The landscape of artificial intelligence is rapidly evolving, with sophisticated models becoming the bedrock of innovative applications. As these models grow in complexity and capability, the challenge shifts from mere creation to efficient, large-scale deployment. This is where high-performance inference frameworks become indispensable, acting as the unseen engines that translate raw computational power into tangible AI-driven outcomes. Among these critical innovations is DeepInfer, a high-performance, large-scale inference framework specifically designed for DeepSeek models, representing a significant stride in operationalizing advanced AI. In the burgeoning world of AI offices, where human experts collaborate seamlessly with AI agents, the underlying efficiency provided by frameworks like DeepInfer is paramount, ensuring that every AI-powered interaction and automated workflow is executed with precision and speed. Nonilion, as a platform for human + AI co-working, understands that the agility and responsiveness of its AI agents are directly tied to the robust inference capabilities that power them.
01Unpacking DeepInfer: What is This Inference Engine and Its Core Purpose?
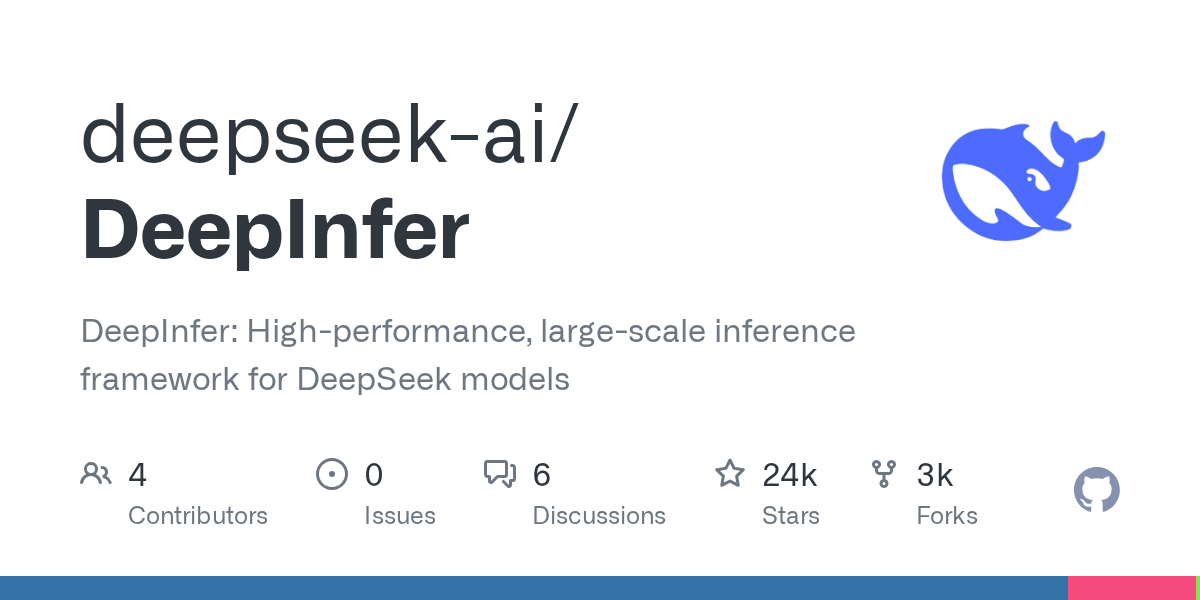
DeepInfer stands out as a specialized inference framework engineered to execute DeepSeek models with exceptional efficiency, particularly within demanding multi-GPU production environments. Described as a high-performance, large-scale inference framework, it is a crucial component for organizations aiming to deploy advanced AI at scale. Its primary purpose is to serve as the inference engine that powers DeepSeek's large-scale production services, embodying what some consider the next operating system for software.
Want your team to run this workflow with AI-native execution?
This robust framework is not merely a theoretical concept; it actively powers DeepSeek-V4.1-Flash, demonstrating its practical application in cutting-edge AI models. DeepSeek has made this in-house inference framework fully open source under the Apache License 2.0, publishing it on GitHub. This move democratizes access to a powerful tool, enabling a broader community to leverage its capabilities for high-performance, large-scale inference with DeepSeek models.
DeepInfer's design philosophy is rooted in maximizing efficiency and scalability. It is built to handle the rigorous demands of real-world AI applications, where speed and throughput are critical. By optimizing the execution of DeepSeek models, DeepInfer ensures that AI agents and systems can respond quickly and process vast amounts of data, making it an foundational technology for sophisticated AI operations.
02The Strategic Importance of DeepInfer for Advanced AI Operations
The ability to deploy AI models efficiently and at scale is a strategic imperative for any organization looking to harness the full potential of artificial intelligence. DeepInfer addresses this need directly by providing a high-performance, large-scale inference framework for DeepSeek models. Its existence enables the operationalization of sophisticated AI technology, moving it from research labs into practical, impactful applications.
In a production environment, especially one leveraging multi-GPU setups, the efficiency of an inference engine directly impacts cost, latency, and overall system responsiveness. DeepInfer's design for these complex scenarios means that DeepSeek models can be run with optimal performance, ensuring that AI-driven services remain fast and reliable. This capability is vital for applications requiring real-time processing or handling massive user loads.
The strategic value of DeepInfer also lies in its open-source nature. By making this powerful framework available, DeepSeek is fostering innovation and collaboration within the AI community. This allows other developers and organizations to build upon a proven, high-performance foundation, accelerating the development and deployment of new AI applications that rely on DeepSeek's models. This approach aligns with the broader industry trend towards shared infrastructure that can elevate the entire ecosystem.
03Technical Foundations: How DeepInfer Delivers Performance at Scale
DeepInfer's high-performance capabilities stem from its specialized design, tailored specifically for DeepSeek models and a select set of high-end accelerators. This focused approach allows for deep optimization that general-purpose inference frameworks might not achieve. The framework is engineered to excel in scenarios demanding significant computational power, making it ideal for the complex calculations inherent in large language models.
To ensure peak performance and stability, DeepInfer has specific build requirements. It operates within a Linux environment and necessitates GCC 13 or a newer version. These prerequisites underscore its commitment to leveraging modern compiler optimizations and system efficiencies, which are critical for an engine designed to operate at the cutting edge of AI inference. This specialization means that while it delivers exceptional performance for its intended use, it is not designed as a drop-in replacement for more generalized frameworks like vLLM.
Its architecture is optimized for multi-GPU production environments, a crucial feature for handling the computational intensity of large-scale AI models. This multi-GPU support allows DeepInfer to distribute the inference workload across multiple processing units, drastically reducing latency and increasing throughput. Such technical prowess is directly relevant to the operational realities of modern AI offices, where AI agents must perform complex tasks rapidly and reliably. For instance, in a Nonilion virtual office, AI agents tasked with sophisticated data analysis or real-time decision-making would rely on such efficient resource utilization to maintain seamless collaboration and achieve async execution of workflows without bottlenecks.
00DeepInfer's Role in the Evolving AI Office: A Nonilion Perspective
The advent of high-performance inference frameworks like DeepInfer is not just a technical milestone; it’s a foundational element for the future of work, particularly within the evolving concept of the AI office. These frameworks enable the sophisticated AI agents that will increasingly populate and drive productivity in such environments. Imagine AI agents capable of understanding complex human requests, synthesizing vast amounts of information, and executing tasks with near-instantaneous responsiveness—this level of capability is directly supported by the efficiency gains provided by engines like DeepInfer.
In an AI office, humans and AI agents collaborate in a shared workspace, blurring the lines between traditional human-only operations and fully automated processes. DeepInfer's ability to provide high-performance, large-scale inference for DeepSeek models means that AI agents can be deployed with the necessary speed and accuracy to handle complex tasks, from intelligent document processing to advanced data analytics. This directly translates into enhanced workflow automation and more effective team coordination.
Consider the Nonilion virtual office environment, where human + AI teams leverage cutting-edge technologies. AI agents within Nonilion, potentially utilizing frameworks like DeepInfer for their core reasoning and response generation, could significantly enhance various aspects of collaboration. For example, during meeting follow-ups, an AI agent could rapidly process meeting transcripts, identify action items, and assign them, all while requiring robust, low-latency inference to prevent delays. Similarly, for async execution of larger projects, AI agents could manage complex dependencies and provide real-time updates, their efficiency underpinned by powerful inference engines. This synergy allows human teams to focus on strategic thinking and creativity, knowing that the operational heavy lifting is handled by highly capable and responsive AI agents, making the virtual office a truly dynamic and productive space.
05DeepInfer vs. The Landscape: Specialization in Inference Engines
The landscape of AI inference engines is diverse, with various frameworks offering different strengths and specializations. DeepInfer differentiates itself by being a highly specialized engine, purpose-built for DeepSeek models and optimized for a specific set of high-end accelerators. This stands in contrast to more generalized inference solutions that aim to support a broader range of models and hardware configurations.
This specialization is a deliberate design choice that allows DeepInfer to achieve unparalleled performance for its intended use case. By focusing its optimizations on the unique characteristics of DeepSeek models, the framework can leverage specific architectural advantages and computational patterns that might be overlooked in a more generic approach. The result is an inference engine that delivers exceptional speed and efficiency when running DeepSeek's AI models.
The implications of this specialization are significant for AI development and deployment strategies. For organizations heavily invested in DeepSeek's ecosystem, DeepInfer offers a clear path to maximizing the performance of their AI applications. However, for those working with a diverse array of models or hardware, a more generalized framework might be necessary. The existence of specialized engines like DeepInfer highlights a growing trend in the AI industry: as models become more complex and diverse, so too will the tools required to deploy them effectively, leading to a fragmented but highly optimized toolchain for different AI needs. This strategic choice underscores the thought leadership in developing solutions that are precisely tuned for specific, high-value applications, rather than attempting a one-size-fits-all approach.
06Frequently Asked Questions about DeepInfer
What is DeepInfer?
DeepInfer is a high-performance, large-scale inference framework specifically designed to efficiently execute DeepSeek models, particularly in multi-GPU production environments. It serves as the inference engine for DeepSeek's large-scale production services.
Is DeepInfer open source?
Yes, DeepSeek has made its DeepInfer inference framework fully open source under the Apache License 2.0. It is published on GitHub, allowing the community to access and utilize it.
What models does DeepInfer support?
DeepInfer is designed to power DeepSeek models. Specifically, it currently supports DeepSeek-V4.1-Flash and is the high-performance inference framework for DeepSeek-V4 models.
What are DeepInfer's system requirements?
DeepInfer's build requirements include a Linux operating system and GCC 13 or a newer version. It is also specialized for a small set of high-end accelerators.
How does DeepInfer compare to other inference engines like vLLM?
DeepInfer is a specialized engine optimized for DeepSeek models and specific high-end accelerators. It is not intended as a direct drop-in replacement for more generalized frameworks like vLLM, which typically aim to support a broader range of models and hardware configurations.
07Key Takeaways: DeepInfer and the Future of AI Production
DeepInfer represents a critical advancement in the operationalization of large-scale AI, offering a high-performance, open-source inference framework tailored for DeepSeek models. Its specialized design for multi-GPU production environments underscores the industry's commitment to efficiency, scalability, and speed in deploying advanced AI. By enabling rapid and reliable inference, DeepInfer not only powers DeepSeek's cutting-edge models but also sets a benchmark for how sophisticated AI can be brought to life in real-world applications.
The strategic decision to open-source DeepInfer further democratizes access to powerful AI infrastructure, fostering innovation and accelerating the pace of development across the AI ecosystem. This move aligns with the vision of a future where AI technology is not just developed but also seamlessly integrated into daily operations, enhancing productivity and unlocking new capabilities.
Ultimately, the advancements embodied by DeepInfer are foundational for the next generation of AI-powered workplaces. In environments like the this platform virtual office, where humans and AI agents collaborate in a shared workspace, the underlying efficiency provided by such inference engines is non-negotiable. DeepInfer's ability to deliver high-performance inference ensures that AI agents can execute complex tasks, facilitate seamless team coordination, and drive workflow automation with the responsiveness and reliability needed for true human + AI co-working, pushing the boundaries of what's possible in a truly intelligent and collaborative future.
08Why This Trend Matters for Nonilion
This trend matters to Nonilion because it points to a bigger change: teams are moving from simple calls toward persistent, AI-supported collaboration spaces. Nonilion can bridge live presence, meeting context, avatars, and follow-up work so the trend becomes a usable workflow instead of a headline.
09Shareable Extracts
The trend is not just "DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office" - it is a signal that team coordination is becoming the next competitive edge.
Hot take: the teams that win from this shift will not be the ones with more meetings; they will be the ones with clearer shared context after every meeting.
If deepinfer: the high-performance engine driving deepseek models in the ai office keeps moving this fast, remote teams need a workspace where conversation, presence, and follow-up stay connected.
DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office The landscape of artificial intelligence is rapidly evolving, with sophisticated models becoming the bedrock of innovative applications.
As these models grow in complexity and capability, the challenge shifts from mere creation to efficient, large-scale deployment.
10Social Hooks
Everyone is talking about DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office. The overlooked part is what happens to team workflows after the headline fades.
The uncomfortable question behind DeepInfer: The High-Performance Engine Driving DeepSeek Models in the AI Office: are teams adapting their collaboration systems fast enough?
This is not a meeting trend. It is a coordination trend, and products like Nonilion sit right in the middle of that shift.
11Sources and Author
Sources
No direct external source URLs were available for this run.
Author
This article on DeepInfer: High-performance, large-scale inference framework for DeepSeek models was generated by the Nonilion AI blog workflow using web research inputs and AI-assisted synthesis.