Home/Blog/Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev
human + AI workflows
Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev
Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev The relentless pace of AI innovation is driving unprecedented demand for computational po
14 MIN READ
17 Oct 2026
human + AI workflows
Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev
The relentless pace of AI innovation is driving unprecedented demand for computational power, primarily fueled by Graphics Processing Units (GPUs). While the promise of AI agents and advanced machine learning models excites, the underlying infrastructure costs can quickly become an unseen burden, impacting budgets and project timelines. Addressing this challenge head-on is crucial for any organization operating in the AI space, particularly for collaborative AI offices like Nonilion, where human and AI agents work in concert. A pivotal tool in this effort is the GPU Terminal by Context.dev, designed to bring transparency and efficiency to GPU resource procurement.
01The Indispensable Role of GPUs in the AI Era
GPUs have evolved far beyond their origins in graphics rendering to become the foundational hardware for modern artificial intelligence. Their parallel processing architecture makes them uniquely suited for the intensive computations required by neural networks, large language models, and complex AI algorithms. From training sophisticated AI agents to powering real-time inference, GPUs are at the heart of nearly every significant AI breakthrough.
Want your team to run this workflow with AI-native execution?
This escalating demand for specialized hardware means that access to efficient, cost-effective GPU resources is not merely an advantage but an operational imperative. As AI projects scale, so too do the computational requirements, leading to significant capital and operational expenditures. Ensuring that these resources are acquired and utilized optimally is key to sustaining innovation and maintaining a competitive edge in the rapidly evolving AI landscape.
02What is GPU Terminal by Context.dev? A Strategic Advantage for AI Operations
At its core, GPU Terminal by Context.dev is a sophisticated monitoring and intelligence platform focused on GPU pricing. It addresses the critical need for cost optimization in AI infrastructure by providing a centralized dashboard that tracks and compares hourly rates from over 100 GPU providers (Source 1, 2). This extensive monitoring is achieved through Context Web Monitors, which continuously track price changes hourly, ensuring users always have access to the most current data (Source 1).
The platform's primary objective is clear: to help users "Never overpay for GPUs again" (Source 1). The dashboard allows users to pick their desired GPU, compare provider offers side-by-side, explore historical price trends, and even check the original source pages for verification (Source 2). This level of transparency and historical data empowers AI teams and agents to make informed, data-driven decisions when procuring essential GPU resources. Context.dev, more broadly, serves as a web data API for AI agents, capable of scraping URLs into LLM-ready Markdown, searching the live web, crawling entire sites, and extracting structured data, making its GPU Terminal a natural extension of its web intelligence capabilities (Source 5).
03Beyond the Hype: Distinguishing GPU Terminal from GPU-Accelerated Terminals
It's important to clarify a common point of confusion: GPU Terminal by Context.dev is distinct from the concept of
GPU-accelerated terminals, which are command-line applications that use a computer's GPU to render text and interface elements. GPU Terminal by Context.dev is instead a market intelligence and monitoring product. Its purpose is not to make a shell run faster, but to help users understand where GPU capacity is available and how much it costs.
This distinction matters because the two products solve entirely different problems. A GPU-accelerated terminal focuses on local display performance. GPU Terminal focuses on infrastructure decisions: which provider offers a particular accelerator, how prices compare, whether rates are changing, and where a team can verify the underlying information. For organizations managing distributed AI workloads, that market visibility can be just as important as the technical performance of the hardware itself.
04The Cost Problem Behind AI Infrastructure
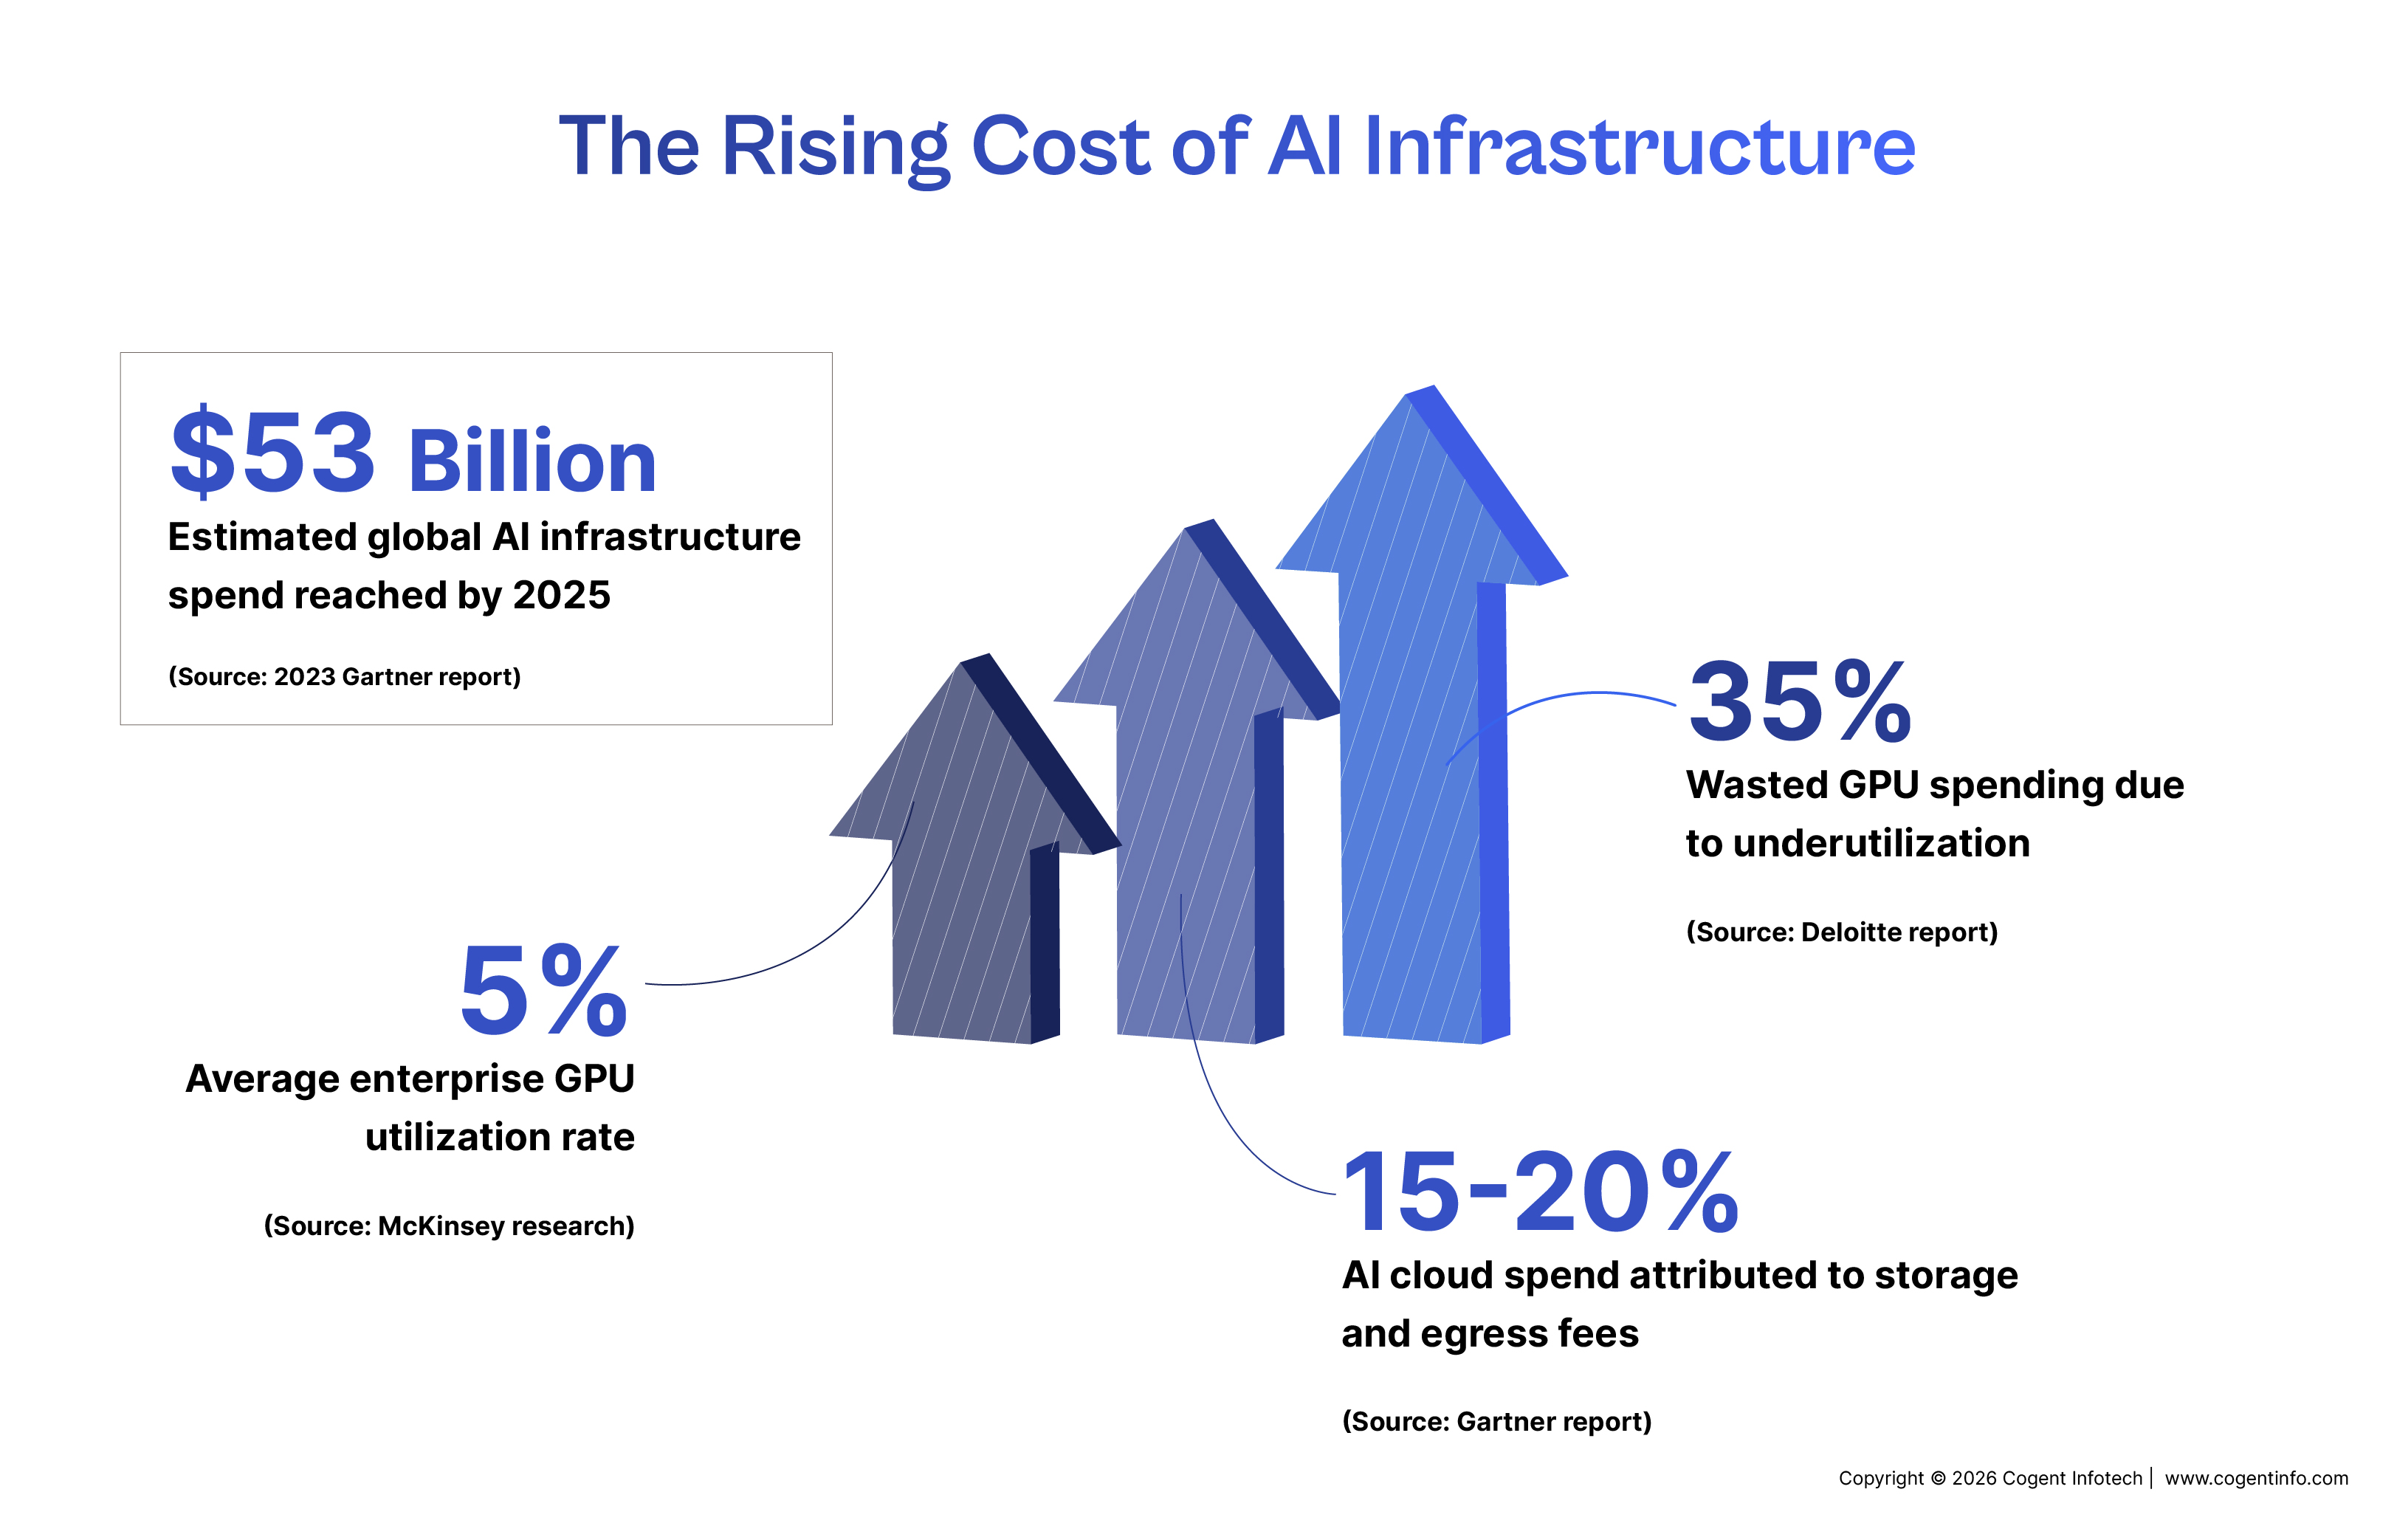
GPU spending is rarely determined by the hourly rental price alone. A seemingly inexpensive instance can become costly when a workload runs for days, requires repeated experimentation, or must be paired with additional storage, networking, and data-transfer services. Teams also need to account for idle time. A provisioned GPU that is waiting for data, a deployment, or human approval still represents a resource commitment.
Several factors make GPU procurement especially difficult:
Different hardware generations: Newer accelerators may provide better performance, while older models may be more economical for smaller workloads.
Variable provider pricing: Rates can differ substantially between cloud platforms, specialized GPU marketplaces, and regional providers.
Workload-specific requirements: Training, inference, fine-tuning, and development may require different memory capacities and performance profiles.
Changing availability: The cheapest provider may not have capacity when a job needs to start.
Unclear comparison points: Providers may describe machines using different configurations, billing terms, or included services.
GPU Terminal helps address the comparison challenge by bringing offers into a common view. Rather than searching through provider pages manually, a user can begin with the GPU model or category they need and examine available pricing information across providers. This does not eliminate the need for technical evaluation, but it creates a more reliable starting point for that evaluation.
05How AI Teams Can Use the Dashboard
A practical workflow begins by defining the workload before selecting a provider. For example, a team preparing to fine-tune a language model might identify its minimum GPU memory, preferred number of GPUs, expected training duration, and tolerance for interruptions. A developer testing an inference endpoint may have different requirements, such as low latency, predictable uptime, or geographic proximity to users.
Once those requirements are established, the team can use GPU Terminal to:
Select the target GPU.
Start with the accelerator class or model that meets the workload's memory and performance needs.
Compare hourly offers.
Review the rates reported across monitored providers rather than relying on a single familiar cloud platform.
Inspect historical movement.
Price history can reveal whether a current offer is typical, unusually high, or part of a broader market trend.
Check the source page.
Verification is important because pricing, availability, and configuration details can change. The original provider page remains the authoritative place to confirm terms.
Estimate the total run cost.
Multiply the hourly rate by expected runtime, then add relevant storage, networking, and operational costs.
Revisit the decision as conditions change.
A provider that is attractive for one experiment may not remain the best option for a later job.
This process is particularly useful for teams that run many short experiments. A small hourly difference may appear insignificant for a single test, but it can become meaningful when multiplied across dozens of experiments, multiple contributors, and longer development cycles.
06Historical Pricing as a Planning Tool
A current price snapshot is valuable, but historical information adds context. Without a time series, a team may mistake a temporary discount for a stable rate or assume that a high price is unavoidable. Historical trends can support more deliberate decisions about when and where to schedule flexible workloads.
For instance, a research team with several non-urgent training jobs may compare current rates with recent price behavior before committing to a long run. If the work can be paused or moved, the team may choose to wait for better availability or select an alternative provider. Conversely, if prices appear to be rising, securing capacity earlier may be preferable.
Historical data should not be interpreted as a guarantee of future pricing. GPU markets are affected by demand, provider inventory, product launches, regional capacity, and changes in billing policies. Its value is instead in improving situational awareness. Teams can make decisions with more evidence than a one-time manual search provides.
07From Price Comparison to Resource Strategy
The most effective use of GPU Terminal is not simply choosing the lowest displayed number. A low hourly rate can be misleading if the instance has insufficient memory, limited availability, poor reliability, or additional charges that materially change the final bill. Cost optimization requires balancing price with suitability and operational risk.
This is where GPU Terminal can function as the discovery layer in a broader procurement process. It can help identify candidates and surface price differences, while engineering and operations teams validate the technical and commercial details before deployment.
For Nonilion and similar collaborative AI environments, this separation of responsibilities can be useful. An AI agent may monitor pricing, identify a shortlist, and report a potential saving. A human operator can then review the provider's terms, confirm that the configuration supports the workload, and authorize the purchase. The result is a workflow in which automation accelerates research without removing human oversight from consequential infrastructure decisions.
08Supporting Agentic Workflows
Context.dev's broader focus on web data for AI agents is relevant to this use case. AI agents often need current information rather than static knowledge captured during model training. GPU pricing is a clear example: a language model may know what a GPU is, but it cannot reliably infer today's provider rates without accessing fresh data.
A pricing-monitoring workflow could allow an agent to answer questions such as:
Which monitored providers currently list the requested GPU?
What are the lowest reported hourly rates?
How has the price changed over a selected period?
Which offers should be verified before procurement?
Is a cheaper alternative available for a development workload?
The agent's output should be treated as decision support, not an automatic purchase instruction. Prices and availability can change between collection and execution, and a provider's listing may not capture every restriction. A robust workflow therefore includes source links, timestamped observations, validation steps, and spending limits.
This approach also improves repeatability. Instead of having each engineer conduct an ad hoc search, an organization can establish a shared process for monitoring, comparison, approval, and documentation. Over time, that process can produce a clearer record of why a provider was selected and how infrastructure costs evolved.
09Building a GPU Cost-Control Practice
GPU Terminal is most effective when paired with basic cost-management discipline. Teams should begin by tagging workloads according to purpose, owner, project, and expected duration. They should also distinguish between persistent services and temporary jobs. This makes it easier to identify which workloads can move to a lower-cost provider or run during a more favorable pricing window.
Useful operational practices include:
Setting budgets for experiments and projects
Recording expected runtime before launching jobs
Automatically shutting down idle instances
Using smaller or older GPUs for development when appropriate
Reserving premium hardware for workloads that genuinely require it
Reviewing actual costs against initial estimates
Documenting provider-specific fees and limitations
Rechecking rates before recurring or long-duration jobs
A price dashboard cannot prevent waste caused by abandoned instances or inefficient code. However, it can make the market side of the problem more visible. When teams combine pricing intelligence with workload monitoring, scheduling, and lifecycle controls, they gain a more complete picture of GPU economics.
10Important Limitations and Verification
As with any monitoring platform, users should understand what the data represents. A listed hourly rate may reflect a provider's published offer at the time it was collected, not a guaranteed rate or confirmed reservation. Availability can change quickly, and the final cost may depend on configuration details that are not visible in a headline price.
Before committing resources, users should verify:
The exact GPU model and memory capacity.
Whether the listed price applies to the required instance configuration.
Billing increments, minimum commitments, and cancellation terms.
Storage, bandwidth, setup, and other additional fees.
Availability in the required region and time window.
Security, compliance, and data-handling requirements.
The provider's policies for interruptions, maintenance, and support.
These checks are not a weakness of price monitoring; they are a necessary part of responsible procurement. The value of GPU Terminal lies in reducing search costs and improving visibility, while final decisions still depend on current source information and the needs of the workload.
As AI development becomes more distributed, GPU procurement will increasingly resemble an ongoing optimization problem rather than a one-time infrastructure choice. Teams may use different providers for prototyping, training, batch inference, and production serving. The best arrangement can change as workloads, prices, and capacity change.
GPU Terminal by Context.dev contributes to this environment by making GPU pricing easier to observe and compare. Its centralized dashboard, provider coverage, hourly monitoring, historical views, and source verification features give AI teams a practical way to turn a fragmented market into actionable information. It does not replace infrastructure expertise, but it can help that expertise operate with better data.
For organizations such as Nonilion, where human and AI agents collaborate on technical work, this transparency is especially valuable. Agents can help collect and organize current market information, while people retain responsibility for validating requirements, managing risk, and approving expenditure. Together, these capabilities support a more disciplined approach to GPU usage—one that treats compute not as an unlimited background resource, but as a strategic input that should be measured, compared, and optimized.
12Why This Trend Matters for Nonilion
This trend matters to Nonilion because it points to a bigger change: teams are moving from simple calls toward persistent, AI-supported collaboration spaces. Nonilion can bridge live presence, meeting context, avatars, and follow-up work so the trend becomes a usable workflow instead of a headline.
13Shareable Extracts
The trend is not just "Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev" - it is a signal that team coordination is becoming the next competitive edge.
Hot take: the teams that win from this shift will not be the ones with more meetings; they will be the ones with clearer shared context after every meeting.
If navigating the gpu frontier: optimizing ai resource costs with gpu terminal by context.dev keeps moving this fast, remote teams need a workspace where conversation, presence, and follow-up stay connected.
Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev The relentless pace of AI innovation is driving unprecedented demand for computational power, primarily fueled by Graphics Processing Units (GPUs).
While the promise of AI agents and advanced machine learning models excites, the underlying infrastructure costs can quickly become an unseen burden, impacting budgets and project timelines.
14Social Hooks
Everyone is talking about Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev. The overlooked part is what happens to team workflows after the headline fades.
The uncomfortable question behind Navigating the GPU Frontier: Optimizing AI Resource Costs with GPU Terminal by Context.dev: are teams adapting their collaboration systems fast enough?
This is not a meeting trend. It is a coordination trend, and products like Nonilion sit right in the middle of that shift.